CAD & 3D Engineering Specification

Cloud Render Farm Architecture

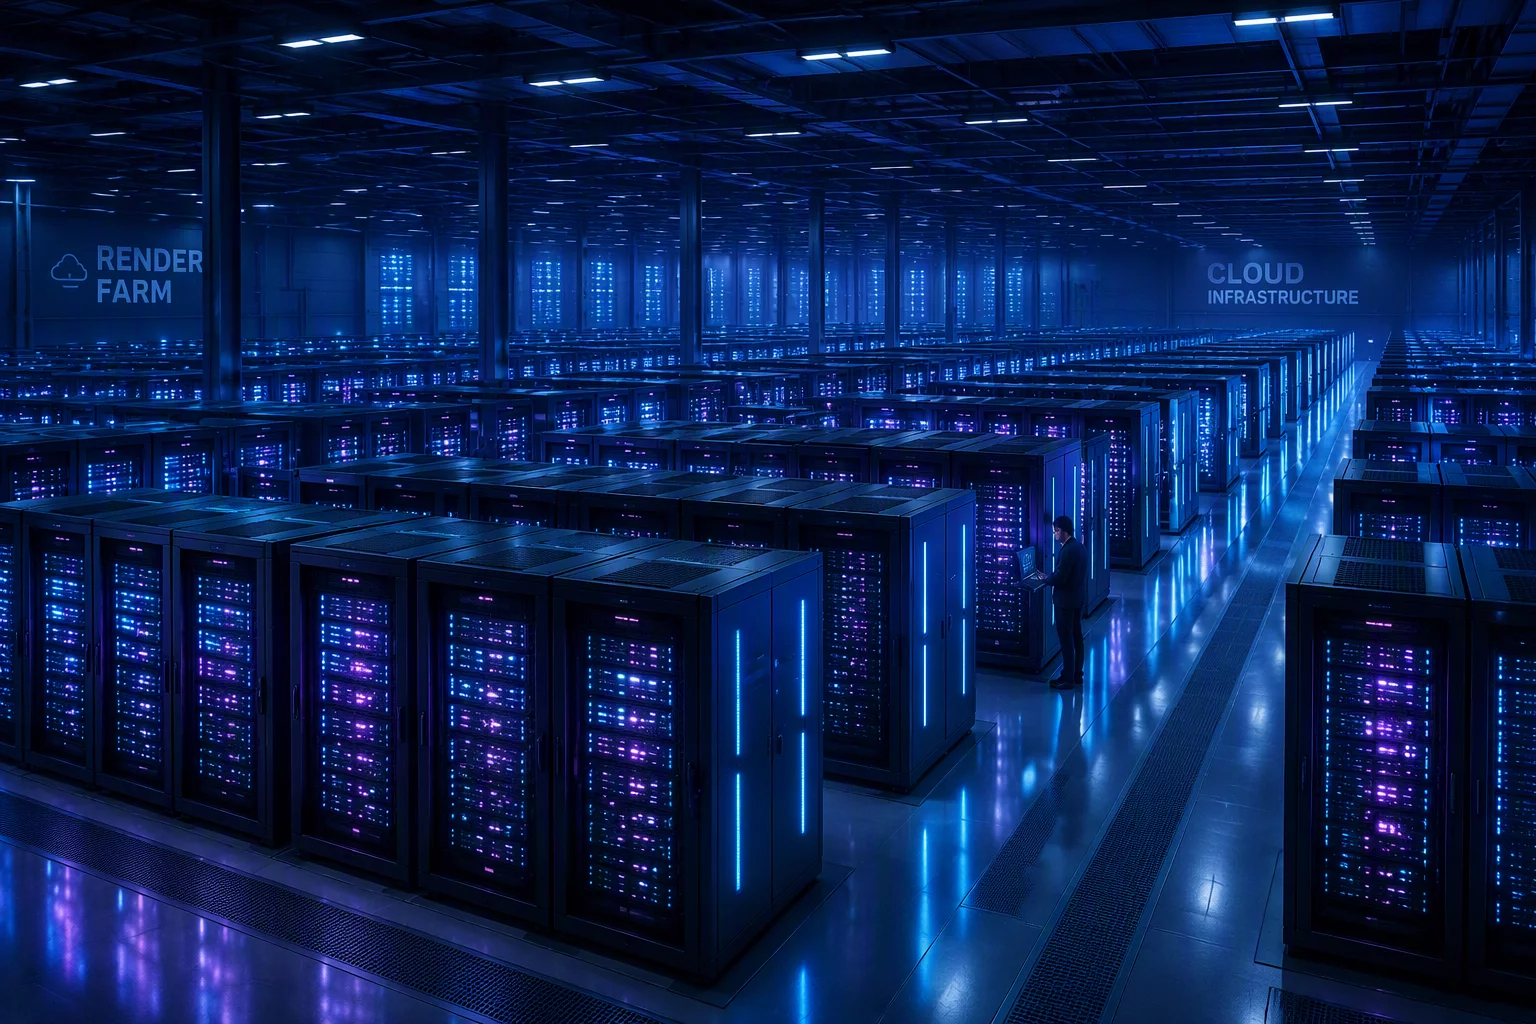
Scalable distributed GPU render clusters, automated task queues, and fault-tolerant cloud pipelines designed for ultra-high-resolution 3D asset processing and animation rendering.

SERVICE FEE $3100
Zero-Tolerance SLA Guaranteed
[NODE::SPEC_VIEWPORT] PIPELINE READY
Cloud Render Farm Architecture
STEP / glTF / FBX / STL TOLERANCE: ±0.005mm

Cloud Render Infrastructure

Managing high-end computational visualization requires balanced node orchestration and reliable network storage backbones. Our cloud render farm architecture establishes automated worker pools configured specifically for Blender Cycles, OptiX, V-Ray, and proprietary raytracing engines.

01
Dynamic Auto-Scaling Worker nodes respond to incoming render queue velocity in real-time.
02
Distributed Storage Caching Low-latency system to synchronize multi-gigabyte texture repositories across nodes.
03
Zero-Loss Checkpointing Automatic task checkpointing and frame re-dispatch on transient instance termination.
04
Encrypted Asset Streaming Pipelines adhering to strict enterprise confidentiality and IP compliance.

By integrating containerized worker images with prioritized workload balancers, render batches execute concurrently across hundreds of GPU compute units, cutting animation sequence compile times by up to 75%.

Technical Parameters

GPU CLUSTER RUNTIME NVIDIA CUDA / OptiX / Metal
TASK QUEUE SCHEDULER Kubernetes / Celery / OpenCue
NETWORK THROUGHPUT 100 Gbps Virtual Fabric
CACHE LATENCY < 1.2 ms NVMe Direct

Package Deliverables

Each farm architecture deployment includes turnkey configuration scripts, container templates, and deployment guides:

  • Terraform and Helm blueprints for multi-cloud node orchestration and auto-scaling rules.
  • Dockerized worker images pre-configured for Blender 4.x/5.x headless Cycles rendering.
  • Centralized web-based job submission portal and frame inspection dashboard.
  • Complete DevOps documentation and security compliance auditing checklist.

Service FAQ & Architecture

The cluster orchestrator continuously monitors queue depth. When pending tasks exceed configured thresholds, spot or on-demand worker instances spin up within 90 seconds, process assigned frame chunks, and terminate immediately after queue exhaustion to minimize compute overhead.

Yes. We implement hybrid VPN mesh tunnels so local studio hardware can handle primary daytime frames while cloud nodes seamlessly absorb overnight batch jobs or high-resolution render peaks.

All assets reside on encrypted storage volumes with TLS in-flight encryption. Worker containers operate in isolated network segments without external internet routing and wipe temporary cache partitions immediately upon job completion.

Clusters scale horizontally up to 256 GPU nodes with automatic load balancing and fault-tolerant frame redistribution across availability zones.

Pricing follows a tiered compute-unit model with volume discounts applied at 500, 2000, and 10000 frame thresholds, including free re-renders for pipeline-caused failures.

Pipeline Client Reviews

Verified engineering feedbacks and geometry logs

No client reviews yet. Be the first to deploy this procedural setup and leave your feedback.

Submit Engineering Feedback

Thank you! Your review has been submitted and is awaiting engineering moderation.